Chapter 3: Risks and Realities
Navigating AI’s Ethical Risks
Algorithmic Bias
AI systems learn from data and use learned patterns to make predictions, classifications, and recommendations, and can sometimes take action on our behalf. Bias can enter at different points along the way, from patterns already present in data to decisions about how a model is trained and where it is eventually used.
Algorithmic bias is a broad term used to describe systematic patterns in an algorithmic system that can lead to unfair or unequal outcomes for different people or groups (Suresh & Guttag, 2021). The different forms of bias we explored, including historical, representation, learning, and deployment bias, can all contribute to these outcomes.
Now, let's follow that bias beyond the system itself. What can happen when biased predictions, classifications, or recommendations infiltrate educational settings? What are the direct impacts on the daily experiences, opportunities, and outcomes of both students and educators?
Real-World Examples of Algorithmic Bias in K-12 Settings
AI Detection Software Bias Against English Language Learners
Why this Matters: Multilingualism is a common feature of Canadian communities and classrooms. More than 4 in 10 Canadians can have a conversation in more than one language, and one in four has at least one mother tongue other than English or French (Statistics Canada, 2022). In British Columbia's public schools, for example, 15% of students were identified as English Language Learners in 2024–25 (British Columbia Ministry of Education and Child Care, 2025).
What Happened: Following the rapid integration of generative AI in education, school districts across North America have been adopting automated text detectors to flag suspected academic misconduct. A landmark Stanford University study evaluated seven leading commercial AI detectors and uncovered severe structural linguistic bias (Liang et al., 2023). Because detectors rely on "perplexity" (measuring vocabulary variability and sentence predictability), the software consistently mistook the formulaic, low-perplexity writing typical of non-native English speakers for machine-generated text.
Outcomes: The study indicated that the algorithms falsely accused non-native English writers of cheating 61.2% of the time, compared to a near 0% false-positive rate for native English writers (Liang et al., 2023). In response, major educational institutions (including Vanderbilt University and multiple K-12 districts across North America) permanently disabled AI detector features. Educational tech providers updated guidance, warning school administrators that automated detector scores must never serve as sole evidence for disciplinary action.
These case studies offer a snapshot of the ways in which algorithmic bias can impact K-12 school systems, illustrating that automated tools do not operate in a neutral vacuum. When trained on unrepresentative datasets or designed without inclusive guardrails, these technologies can actively reinforce systemic inequities, misinterpret the actions of marginalized groups, and limit educational opportunities. To foster truly equitable learning environments, school communities must critically evaluate the models they deploy, ensuring human oversight and accountability remain at the center of administrative and instructional decisions.
Hallucinations & Inaccuracies
To understand why AI models produce false information, we can return to Chapter 2, where we learned that a large language model generates a response by predicting what is likely to come next based on patterns learned during training. AI models do not “know” facts or verify truth, they calculate the statistical probability of which word or token should follow the previous one based on patterns learned during training.
An AI hallucination occurs when a model confidently generates completely false information, fabricates historical events, invents scientific claims, or generates realistic-looking academic citations and URLs that do not exist in reality.
Key drivers of AI hallucinations and inaccuracies include:
Knowledge Cutoff
Many large language models are trained on a static snapshot of historical data that ends at a specific point in time, known as a knowledge cutoff (or training cutoff). This means they may not know about new events, policy changes, or scientific discoveries that happen afterward. When asked about something beyond their training, they may not realize their information is missing or outdated. Instead of admitting they don't know, they may generate an answer that sounds convincing but includes made-up facts or outdated information.
The "Fluency Illusion"
Because large language models excel at mimicking professional, academic grammar and authoritative tone, fabricated outputs are presented with persuasive fluency. As a result, users frequently fall victim to the "fluency illusion," (Benjamin, 1998) mistaking linguistic polish for factual accuracy.
Why does this matter?
While these examples can seem like minor errors to some, they highlight the importance of AI literacy and professional judgment when considering the use of AI in education. It is important that educators are able to critically evaluate AI-generated content. This discernment involves being able to recognize manipulated or fabricated images, identifying inaccuracies, and verifying information before sharing it with students. We will practise this competency in Chapter 4: Daily Practice and Classroom Integration.
Deepfakes & Synthetic Media
As generative models expand beyond text into multimodal formats, seeing and hearing are no longer enough to establish authenticity. Multimodal outputs can produce synthetic media, which refers broadly to any digital content (including written text, imagery, voice and music, video, 3D digital assets, virtual avatars, and simulated environments) that is generated, augmented, or manipulated by AI models. Unlike traditional digital media editing, which requires technical skill and manual software manipulation, synthetic media tools operate through prompt-driven generative models that construct realistic digital media at scale.
Deepfakes represent a specialized subset of synthetic media created using deep learning algorithms to swap faces, clone human voices, or manipulate video footage to depict individuals saying or doing things they never did.
For example, the image below illustrates Albert Einstein shopping in an Apple store, an event we recognize as historically impossible.
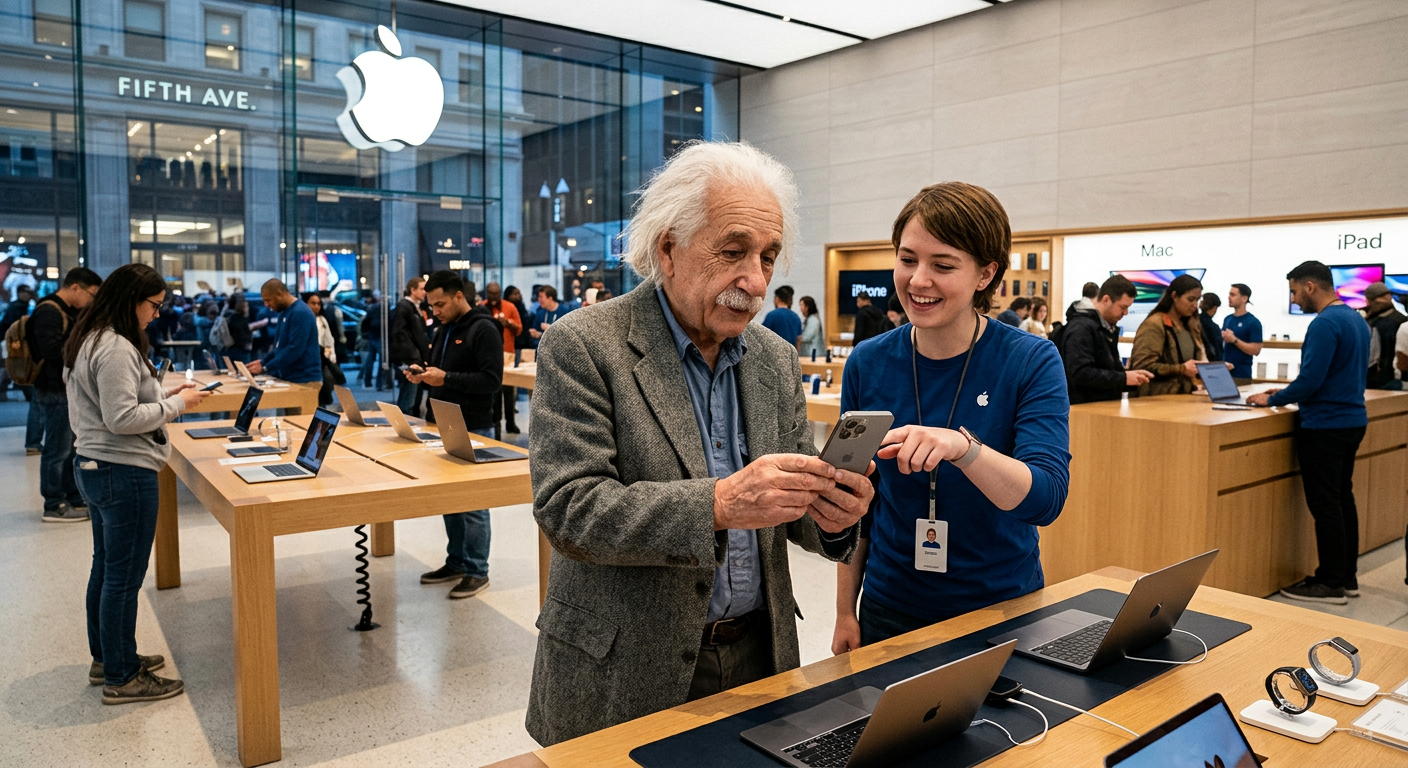
However, many deepfakes are significantly more malicious in nature than our Albert Einstein image. In K-12 education, the proliferation of deepfakes fundamentally alters the landscape of digital media literacy. Beyond simply identifying misinformation or biased text, students must also be able to critically evaluate the authenticity of media in an environment where visual, auditory, and video evidence can be convincingly synthesized or manipulated.
Example: In 2024, a fake audio recording circulated at Pikesville High School in Maryland that appeared to capture the school principal making racist and antisemitic remarks. Authorities alleged that the principal’s voice had been cloned and manipulated using AI. The recording spread through email and social media, resulting in significant consequences for the school community, including the principal being placed on leave and receiving threats and harassment (Finley, 2024).
This case demonstrates how synthetic media can create real-world harm even before it is authentically validated. In school environments, manipulated audio, images, or video can damage reputations, disrupt school communities, and make it increasingly difficult for students and educators to determine what evidence they can trust.
This shift presents distinct educational and safety challenges in school environments:
Traditional digital literacy taught students that some images and video were reliable primary sources. Synthetic media requires students to move beyond surface-level appearance and adopt verification practices like cross-referencing sources, examining provenance, and analyzing contextual clues.
Navigating the complexities of synthetic media highlights how digital interactions are increasingly shaped by simulated realism. As students learn to critically evaluate the authenticity of media generated by synthetic models, they also face a related challenge: engaging with conversational AI designed to simulate human empathy. Beyond discerning real media from fabricated content, learners must navigate the emotional boundaries and social-emotional risks of interacting with AI companions.
AI Companions & Emotional Risk
The rapid rise of conversational AI agents designed with highly empathetic, polite, and personalized dialogue capabilities has led to a growing phenomenon: students interacting with chatbots as "AI companions," digital confidants, or virtual friends.
While conversational agents can offer low-stakes language practice or interactive tutoring, their anthropomorphic design introduces significant social-emotional and psychological risks for young learners (UNICEF, 2025).
Over-relying on AI for emotional validation can substitute for real-world peer relationships, compounding social isolation and hindering the development of interpersonal conflict-resolution skills.
Setting Boundaries & Safeguards
As the risks of anthropomorphic AI become clearer, educators and policymakers are moving to restrict or ban these systems in K–12 environments, demonstrated by bodies such as the Alberta Teachers’ Association (2026). This shift highlights a crucial reality: automated tools cannot replace trained human professionals in core support roles like school counseling, where authentic empathy and ethical judgment are non-negotiable.
To help manage these risks, students need explicit instruction on the inner workings of AI systems, helping them recognize that these models are non-sentient computational tools rather than substitutes for genuine human relationships.